Blog · AI for small and midsize businesses
Scanned PDFs and scattered documents: what AI search needs
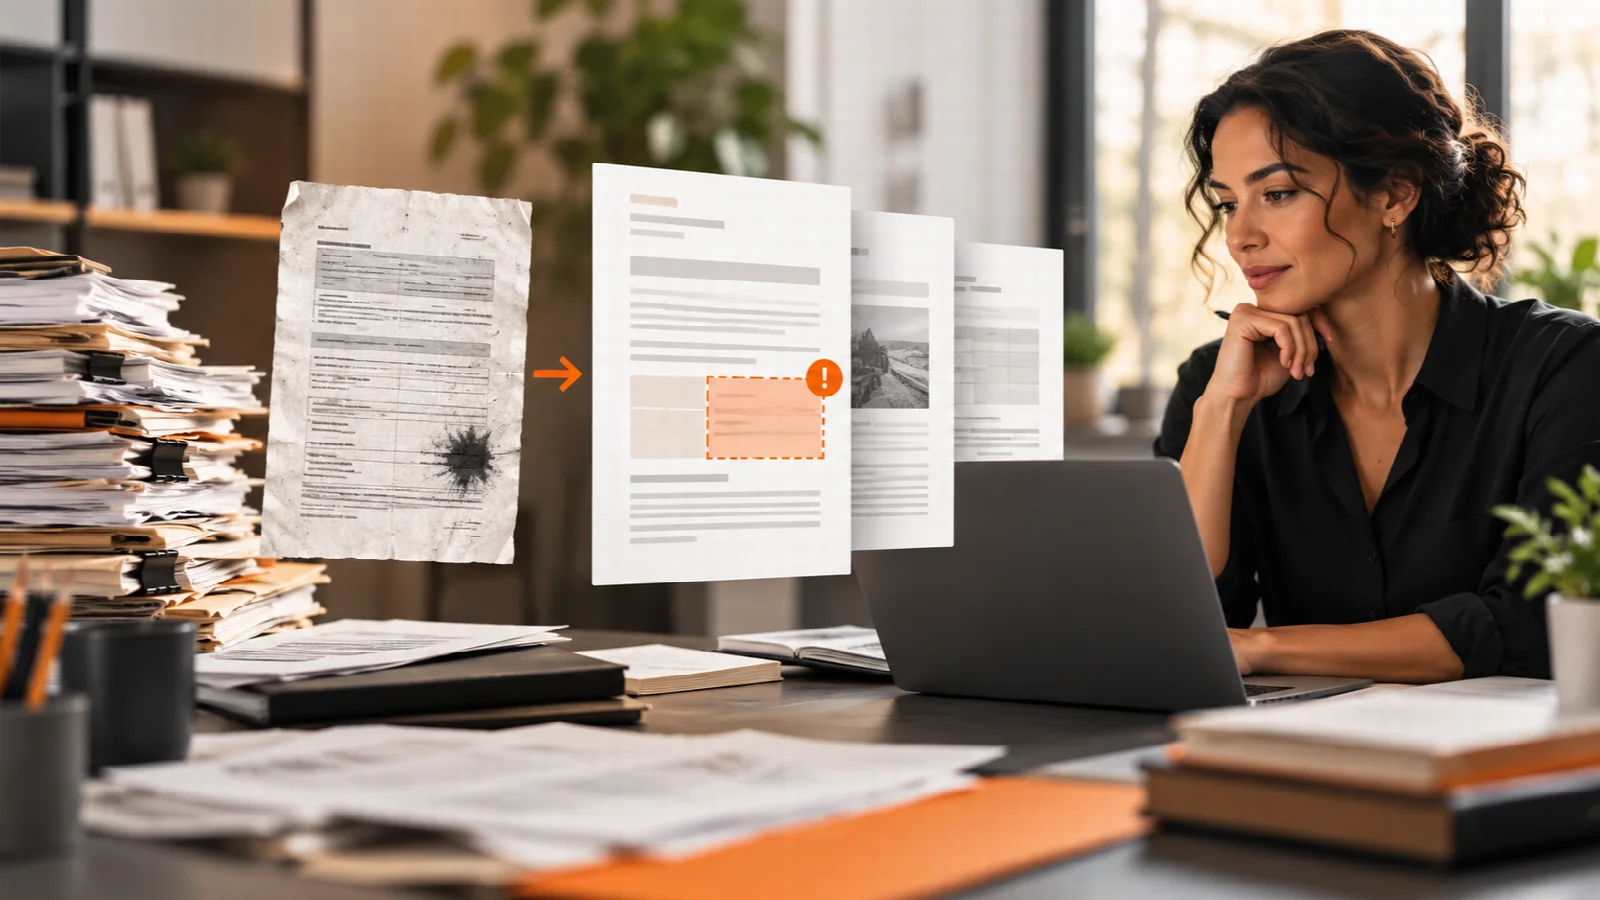
A scan can look clear to a person while producing broken text for a search system. Inspect extraction before tuning the assistant. A small before-and-after test reveals missing characters, detached table headers and lost page references that a fluent answer can otherwise conceal.
In this article
An assistant cannot reliably find a product code that disappeared during extraction. Scanned PDFs are images of pages; optical character recognition, or OCR, attempts to turn those images into searchable text. That step needs its own quality check before you judge the search or answer.
Check the accuracy of the extracted text
Open the extracted text beside the original page. Check identifiers, decimal marks, units, accents, headings and reading order. Multi-column pages can merge sentences. Table values can become detached from their headers, leaving text that is readable but misleading.
The Microsoft RAG overview includes OCR and document extraction among content-preparation capabilities. Capability does not establish extraction quality for your files. Use representative layouts and poor scans, not only clean samples.
A before-and-after search test
- Select permitted pages from ordinary scans, tables and difficult layouts.
- Have the document owner mark the exact passage or cell needed for each question.
- Run extraction and inspect whether that evidence survives correctly.
- Search for both exact identifiers and natural questions.
- Check the retrieved passage, final answer and ability to open the source page.
- Correct extraction or structure, then repeat the same questions.
Keep an issue log with document ID, page, defect, affected question, owner and retest result. This separates extraction failures from search failures and interpretation errors.
An illustrative catalog page
Suppose a hypothetical scan contains two components, X-10 and X-100, with different pressure limits. OCR confuses the final zero and loses the column heading. Searching may retrieve a plausible page while the answer assigns the wrong limit to the product.
The catalog owner verifies both identifiers and their row-column relationships. The technical team can preserve the table structure, add approved structured attributes or exclude the damaged section pending correction. Simply asking the model to be more careful does not restore the missing evidence.
Preserve document identity
Each extracted passage needs a stable document identifier, edition and page reference. Keep the original available to authorized users. Remove repeated headers where appropriate without discarding useful headings or conditions. When splitting long material into smaller searchable passages, retain the context needed to interpret each part.
Microsoft's design guide recommends representative test material and evaluation of each stage. The document owner confirms that meaning is preserved; the technical lead verifies extraction and retrieval behavior.
Keep corrected examples as regression tests. If a new extraction setting improves one table, verify that it did not damage reading order elsewhere. Record both the original and corrected evidence, including the accepted identifier. Prioritize defects by business consequence: a missing decorative footer is different from a lost negative sign, unit or exclusion that changes an answer.
Measure field accuracy for important identifiers, successful retrieval of expected evidence and source-opening success. For broader preparation, use the company knowledge guide. Bring difficult pages and test questions to a RAG readiness review before importing the entire archive.